From Pixels to Cloud Dollars — a Reproducible Research Pipeline
CloudSight AI v3.0 synthesises a 600-image, 6-class dataset at 224 px, benchmarks five CNN architectures fairly, evaluates a two-stage detector against COCO ground truth with mAP@0.5 = 97.5%, and converts detections into a monthly cloud bill — every number computed live, nothing hardcoded.
Full pipeline: ≈ 15–25 min on free CPU · ≈ 4 min (T4) on Colab GPU · zero configuration.
600
HD renders @ 224 px
6
Classes × 100 images
5 / 5
Models at 100% test acc
40
COCO scenes · 234 boxes
97.5%
mAP@0.5 (VOC-style AP)
± 0.00
Seed variance · 3 seeds
2 / 2
FinOps bills reconcile exact
15–25 min
Full run on free CPU
Methodology
What Was Done, Where, and How
Eight verified stages — the exact sequence the notebook executes on every run. Where it runs: Google Colab (CPU or T4 GPU) or any local Python 3.12 box. How: Runtime → Run all.
Runtime
≈ 15–25 min CPU · ≈ 4 min (T4) GPU
Reproducibility
seed 42 · deterministic RNG everywhere
Dependencies
torch · torchvision · OpenCV · pandas · scikit-learn
You get
600 images · 40 scenes · 5 models · detector · bills
Results
A Fair Five-Way Benchmark — Actual Numbers
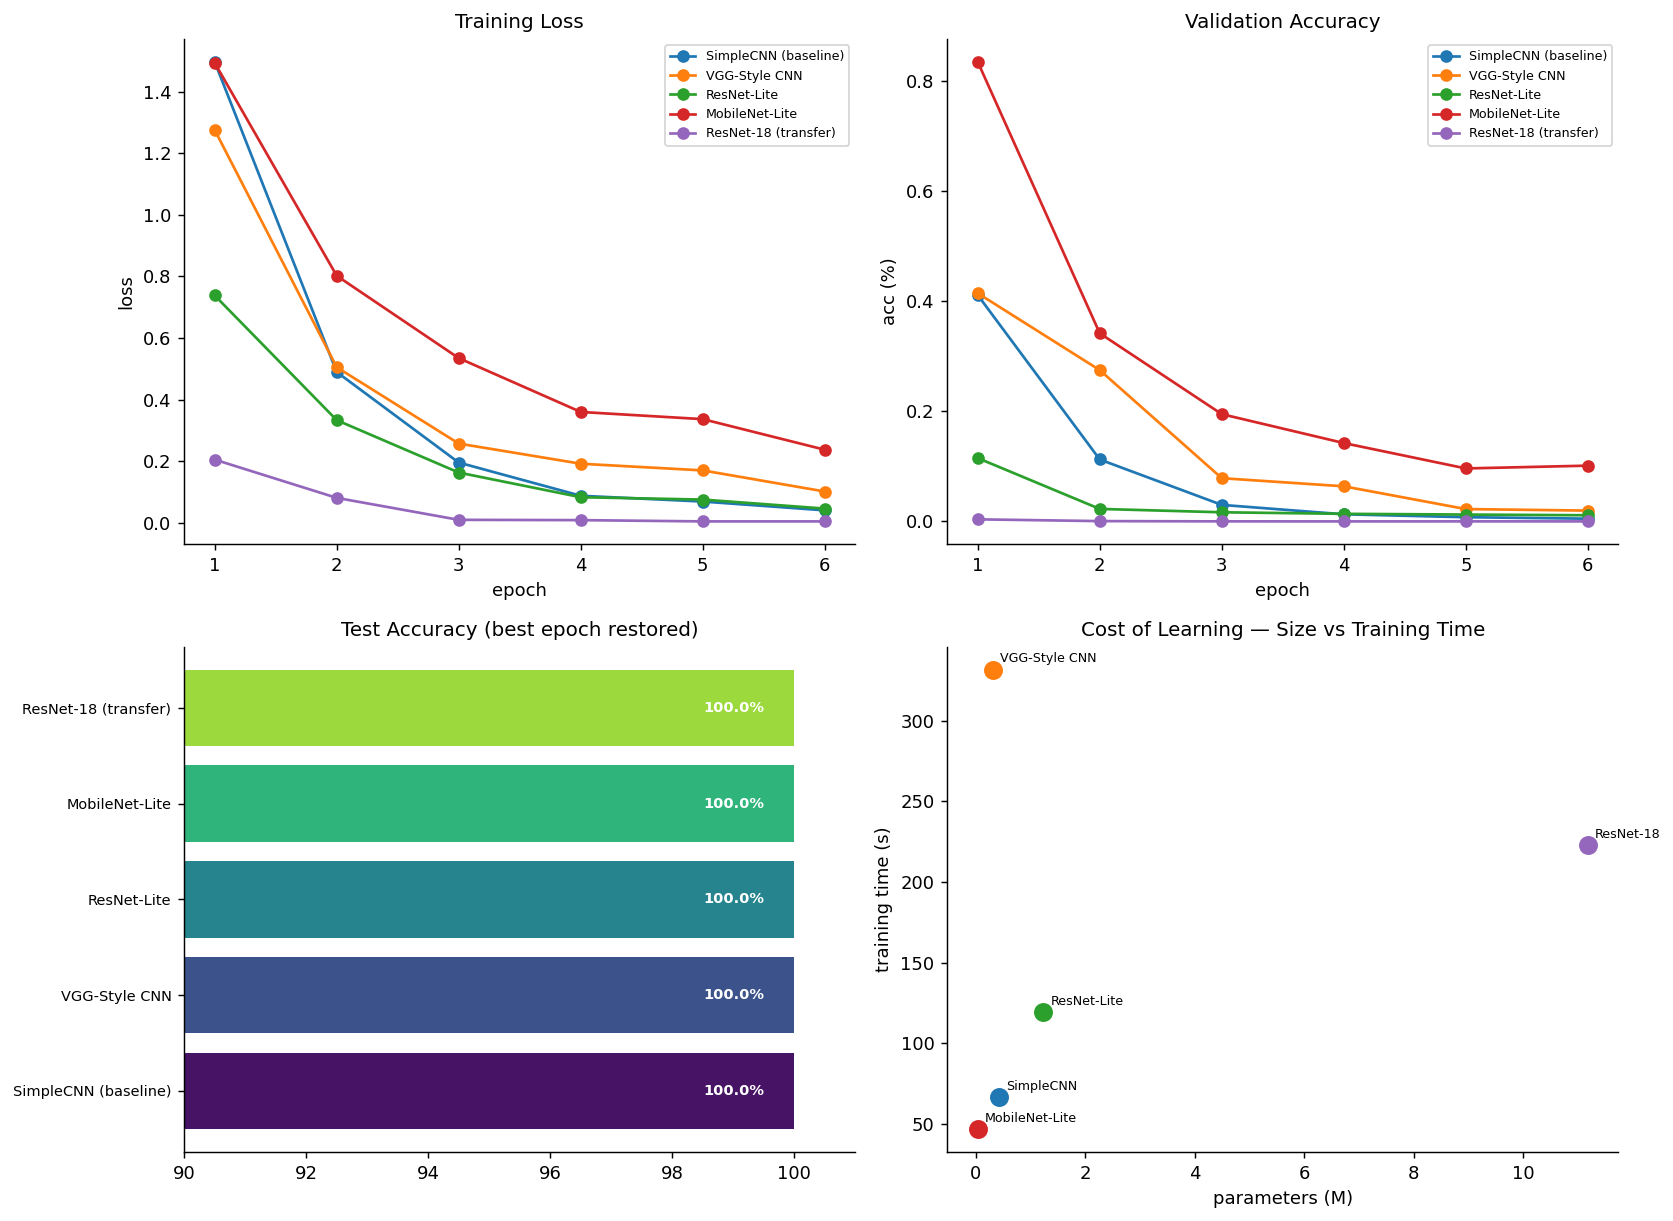
Same loaders, same 6 epochs, same seed — only the architecture changes. Every figure below is the real output of the verified run.
Champion · wins on efficiency
SimpleCNN (baseline)
| # | Model | Acc % | F1 % | Params (M) | Time (s) |
|---|---|---|---|---|---|
| 1 | SimpleCNN (baseline)CHAMPION | 100.00 | 100.00 | 0.43 | 66.6 |
| 2 | VGG-Style CNN | 100.00 | 100.00 | 0.31 | 331.7 |
| 3 | ResNet-Lite | 100.00 | 100.00 | 1.23 | 119.0 |
| 4 | MobileNet-Lite | 100.00 | 100.00 | 0.03 | 46.7 |
| 5 | ResNet-18 (transfer) | 100.00 | 100.00 | 11.18 | 222.9 |
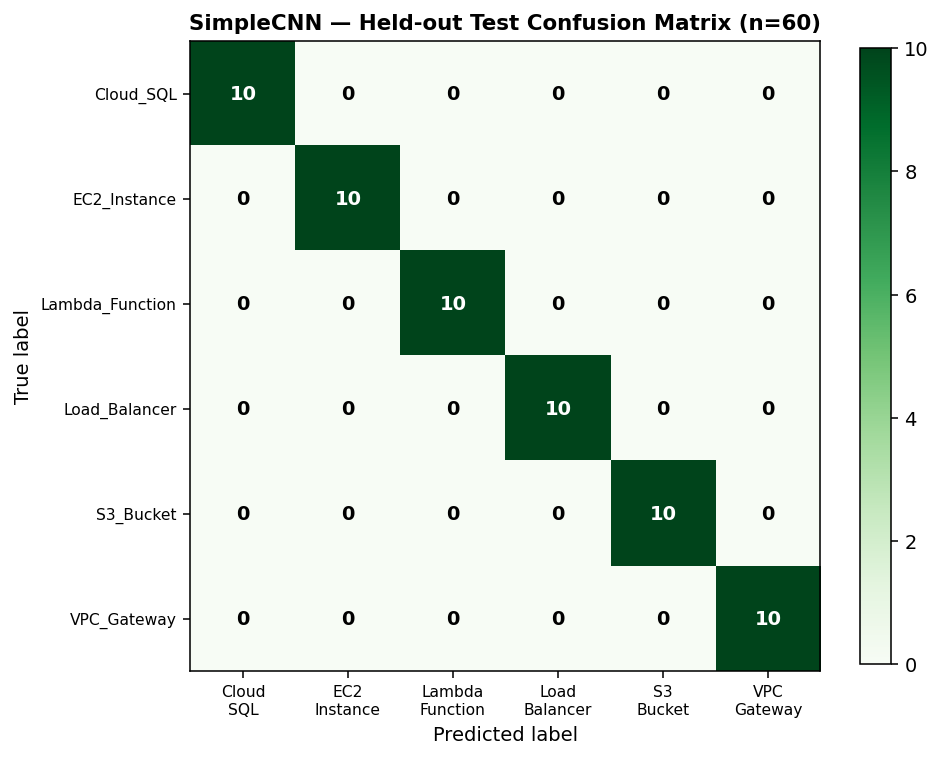
100.00% ± 0.00
Test accuracy and macro-F1 identical across 3 independent runs — a claim of "100%" backed by variance analysis.
Detection
Measured Against COCO Ground Truth
An R-CNN-style two-stage detector: multi-cue saturation proposals → champion CNN scoring → NMS. Quality is computed with proper VOC-style AP — missed instances cap recall, so numbers can't be inflated.
| Class | TP | FP | FN | P % | R % | F1 % | AP % |
|---|---|---|---|---|---|---|---|
| Cloud_SQL | 38 | 0 | 0 | 100.0 | 100.0 | 100.0 | 100.0 |
| EC2_Instance | 42 | 0 | 0 | 100.0 | 100.0 | 100.0 | 100.0 |
| Lambda_Function | 35 | 9 | 0 | 79.5 | 100.0 | 88.6 | 97.9 |
| Load_Balancer | 31 | 1 | 1 | 96.9 | 96.9 | 96.9 | 96.9 |
| S3_Bucket | 38 | 6 | 4 | 86.4 | 90.5 | 88.4 | 90.2 |
| VPC_Gateway | 45 | 0 | 0 | 100.0 | 100.0 | 100.0 | 100.0 |
3 of 6 classes are perfect (100% P/R/F1). The misses concentrate where icons of the same class sit close together: their saturated regions merge into one proposal, so the detector under-counts.
False positives come from background textures producing a confident crop — the reason the 0.90 confidence gate exists.
These errors are documented, not tuned away. A learned proposal network (RPN / YOLO baseline) is the clear next step — see the report's future-work section.
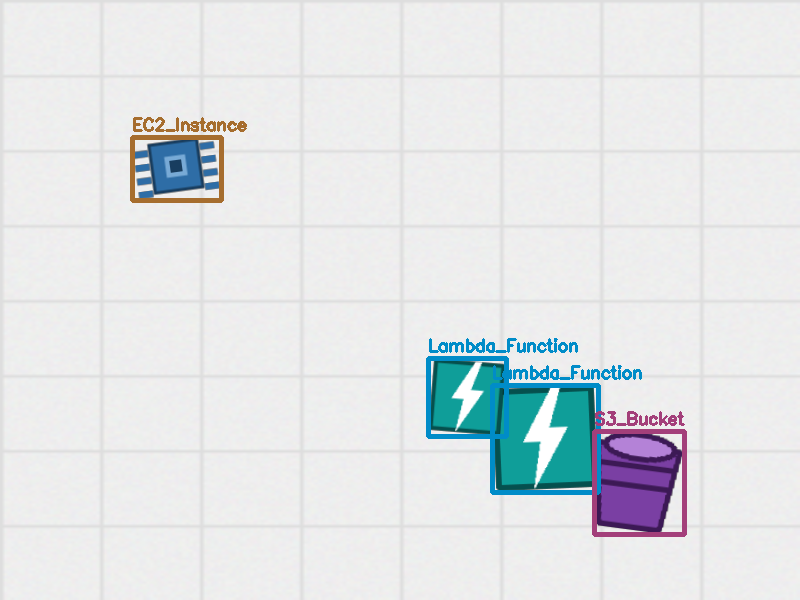
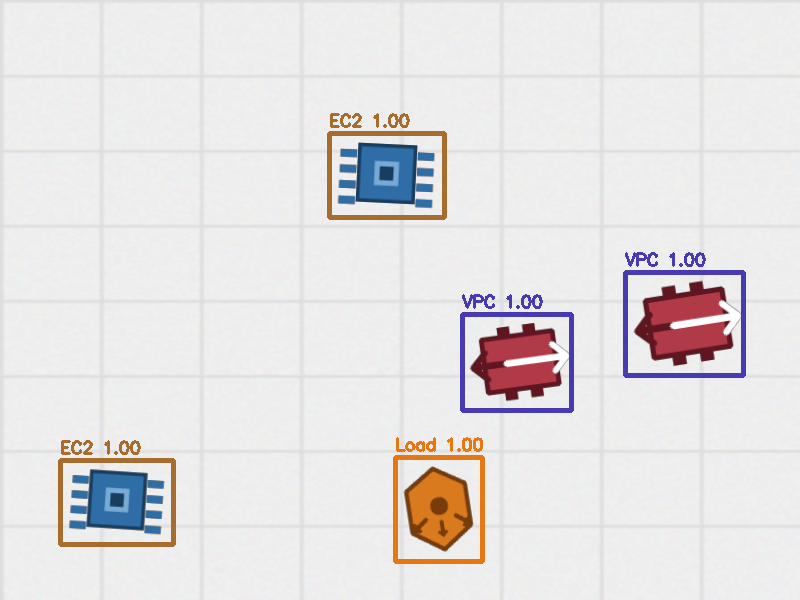
Ground truth (COCO)
boxes straight from annotations.json
Detector — scene 000
5/5 instances · conf ≥ 0.90
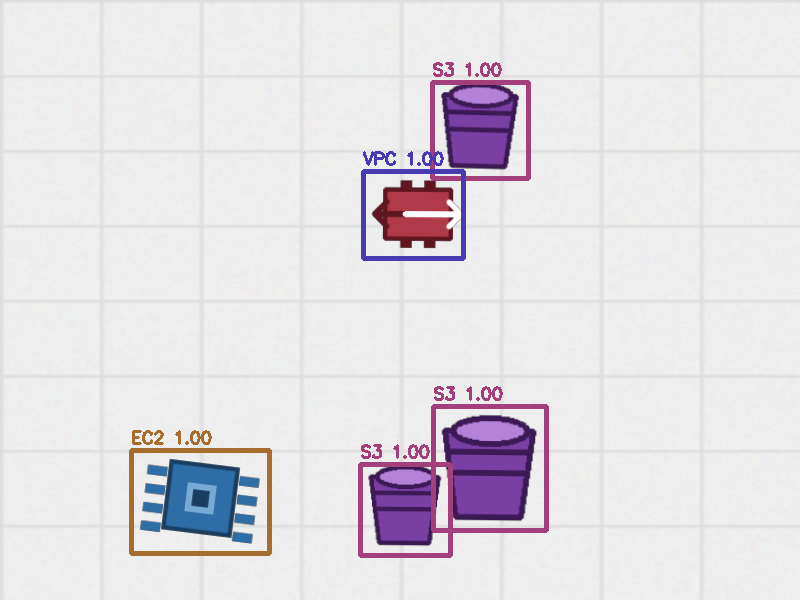
Detector — scene 003
5/5 instances · bill reconciles exact
FinOps
From Pixels to Dollars — Reconciled Exactly
The detector's inventory is multiplied by monthly unit prices, then checked against the COCO ground truth. Both demo scenes match to the cent.
EC2 Instance
$45.50
/ month
Cloud SQL
$120.00
/ month
Load Balancer
$18.00
/ month
S3 Bucket
$12.50
/ month
Lambda Function
$35.00
/ month
VPC Gateway
$28.00
/ month
| Resource | GT | ML | Line total |
|---|---|---|---|
| EC2 Instance | 2 | 2 | $91.00 |
| Load Balancer | 1 | 1 | $18.00 |
| VPC Gateway | 2 | 2 | $56.00 |
| Total / month | $165.00 | $165.00 |
| Resource | GT | ML | Line total |
|---|---|---|---|
| EC2 Instance | 1 | 1 | $45.50 |
| S3 Bucket | 3 | 3 | $37.50 |
| VPC Gateway | 1 | 1 | $28.00 |
| Total / month | $111.00 | $111.00 |
$165.00 + $111.00 — both bills reconcile exactly with ground truth.
In production, the per-class P/R table above is the honest error model for billing confidence.
The Dataset — Live Preview
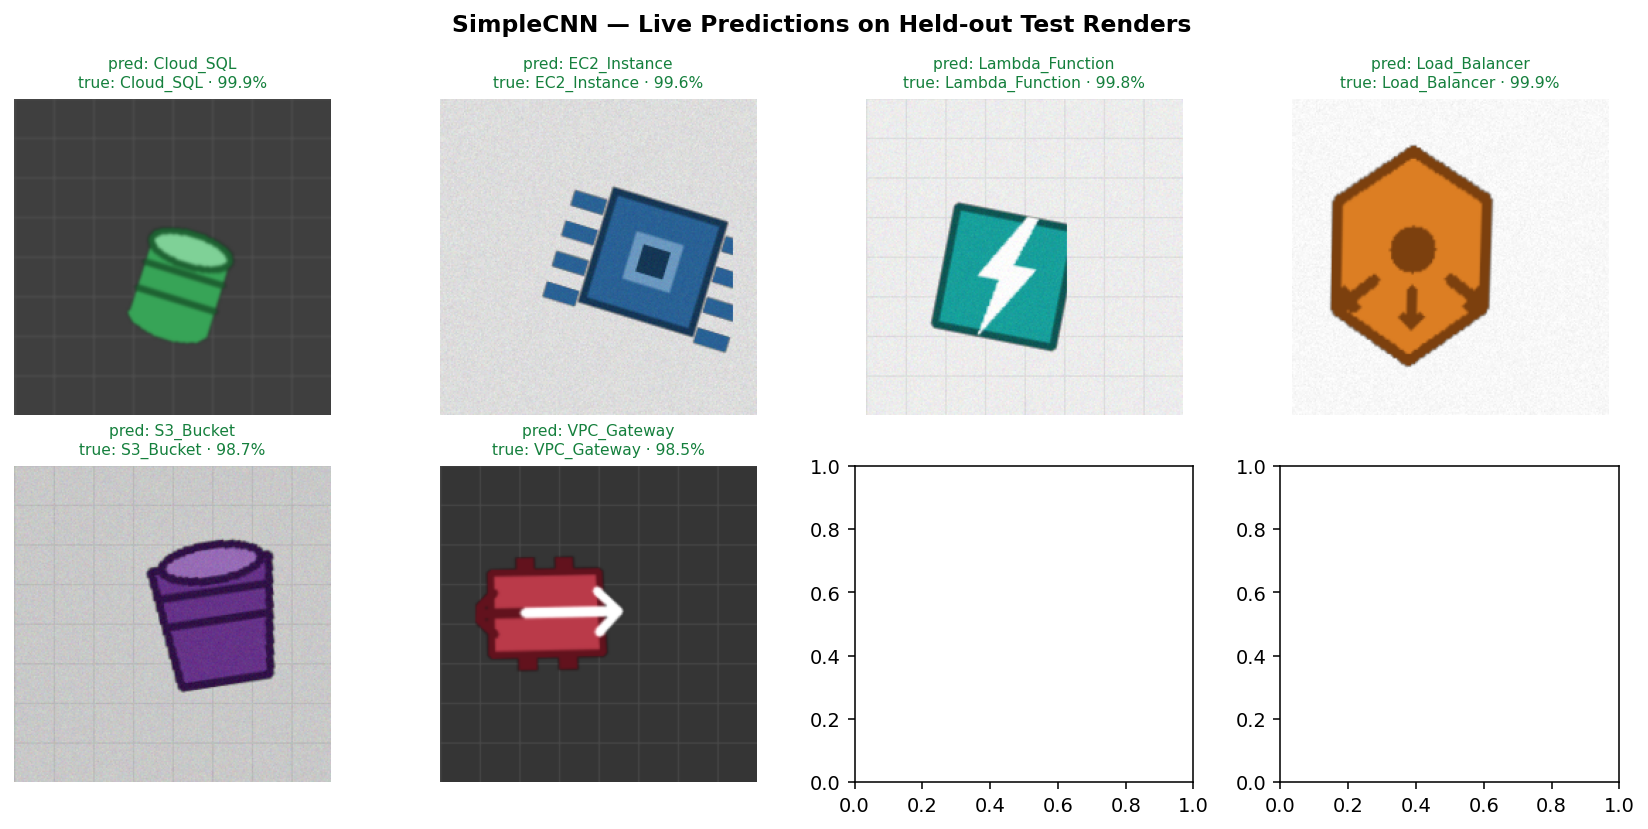
Real 224 px renders produced by the notebook's synthetic engine (6 classes × 100 images, seed 42) plus COCO-annotated detection scenes. Everything on this page comes from the verified end-to-end CPU run — nothing is mocked.
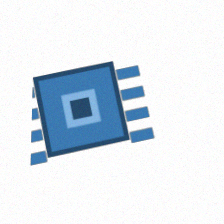
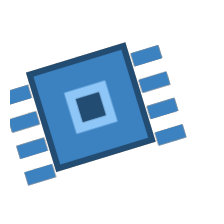
EC2 Instance
Compute chip — square body, dual pin rows · billed $45.50 / month · 224×224 px
Scenes & Ground Truth vs Detector Output
40 independent 800×600 scenes (4–8 icons each) ship with machine-readable COCO ground truth in annotations.json — the same contract real detection datasets follow. Below: the raw composite, its ground truth, and what the two-stage detector actually found.
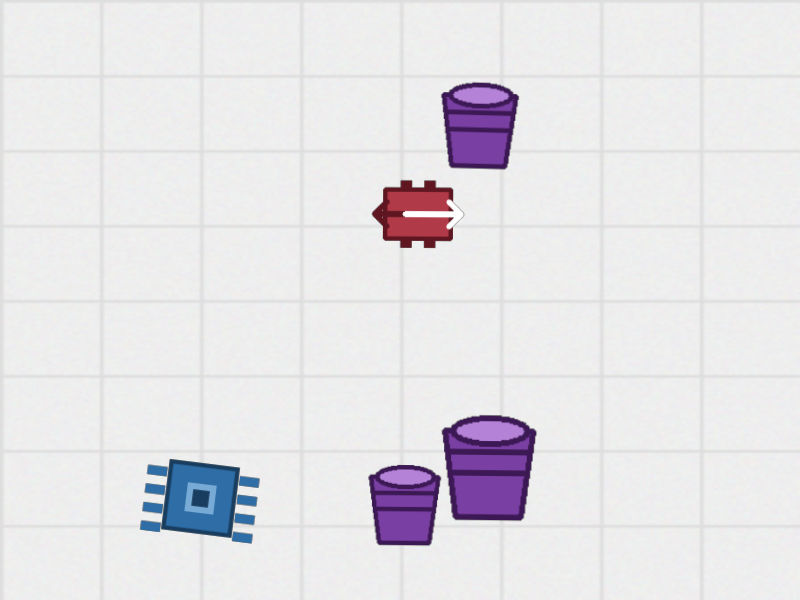
Raw scene 003
800×600 composite — no overlays
Ground truth (COCO)
boxes come from annotations.json, not hand drawing
Detector output — scene 000
5/5 instances found · bill reconciles EXACT
Detector output — scene 003
5/5 instances found · bill reconciles EXACT
Run It Yourself
How to Run in Google Colab
Five steps, zero configuration. The notebook was verified end-to-end on CPU before publishing — the same code path you will execute.
Runtime
≈ 15–25 min CPU · ≈ 4 min (T4) GPU
Reproducibility
seed 42 · deterministic RNG everywhere
Dependencies
torch · torchvision · OpenCV · pandas · scikit-learn
You get
600 images · 40 scenes · 5 models · detector · bills
Get Everything
Downloads & Source
Notebook, full dataset, the written research report and the dataset card — plus how to mirror it all on GitHub.
git init && git add . && git commit -m "CloudSight AI v3.0"
git remote add origin git@github.com:YOU/cloudsight-ai.git
git push -u origin main
Reproduce the whole study in one click.
Open Colab, upload the notebook, hit Run all — ≈ 15–25 min later you have every table, figure and artifact on this page.